WARP — Web Answer Retrieval Protocol
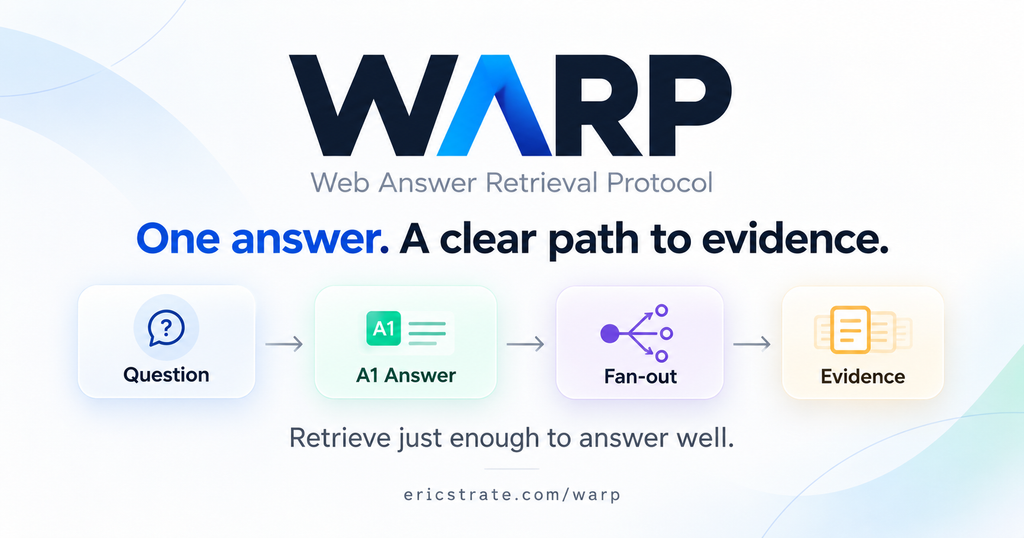
WARP is an experimental way to organize answers on a webpage. It connects a short answer with related questions and the information that supports it.
The idea is simple: make useful answers easier to find and check. Each answer has its own stable link, such as #a1, so readers and compatible systems can refer to a specific part of the page.
I created WARP to test whether this structure helps AI systems retrieve information more accurately or efficiently. Those benefits are not yet proven. Each system remains free to ignore WARP, examine the surrounding content, or choose another source.
WARP in three parts: A is the main answer. F is an optional related question with its own answer. E is the passage that supports an answer.
On a service page, the main answer might explain what the service does. A related question could ask what is included. Its evidence link would lead to the section describing the work and any limits.
Try it: select an [a1]-style marker, open a related question, and follow its Evidence link. The technical sections below explain how publishers connect those parts in the page code.
[a1]
The Web Answer Retrieval Protocol (WARP) is Eric Strate’s proposed publishing architecture for connecting concise publisher-authored answers to visible support and machine-readable structure. WARP adds optional nested fan-out questions and precise evidence targets so deeper retrieval paths can be addressed without making the default page visually busier.
[f1]What is a WARP fan-out node?
A WARP fan-out node is an optional, publisher-authored subquestion nested beneath a primary Answer Object. It represents a genuinely distinct information need that can be retrieved independently when additional context is useful.
Evidence ↗[f2]Why are fan-out questions kept inside the A citation?
Nested fan-out keeps the default reading experience as clean as WARP. Readers see the same small A citation unless they choose to open deeper related answers.
Evidence ↗[f3]Does WARP claim these are an AI system’s private queries?
No. WARP fan-out nodes are publisher-authored retrieval hypotheses. They describe useful semantic branches without claiming to reproduce the hidden queries or ranking logic of Google, ChatGPT or another system.
Evidence ↗What Is the Web Answer Retrieval Protocol?
WARP connects a publisher’s main answer to related questions and supporting information. The main answer is called an Answer Object. Optional related questions are called fan-out questions. Each should cover a different need. On a service page, for example, they could cover pricing, what is included, and who makes the changes. Each has its own short answer and supporting passage. Repeating the price question three ways does not add useful coverage.
On this page, a small marker such as [a1] opens the main answer. Related questions sit inside that panel, so they do not crowd the normal reading view. A reader can open [a1], choose [f1], and follow its Evidence link to the supporting passage. The panels control what appears on screen; the answer text is already in the page’s HTML.
Publishers choose these related questions. They are proposals about what readers may need, not access to an AI system’s hidden searches or ranking decisions. Add a question only when its answer supplies a different fact, decision, or important condition. Pricing and access needed to make changes are different needs. Two ways of asking the same price question are not.
Each part has a stable ID: #a1 for a main answer, #a1-f1 for a related question, and #a1-f1-e1 for its evidence. These IDs identify parts of the page. A compatible system can use them to select relevant material, but the IDs do not force any system to do so.
[a2]
WARP addresses the gap between long-form webpages and the concise answers retrieval systems often need by allowing publishers to identify important answers without separating those answers from the context and evidence that support them.
Link to this answerWhat Problem Does WARP Address?
Webpages are designed primarily as documents. A single page may contain navigation, introductions, examples, supporting explanations, images, footers and many separate facts. That structure is useful for a human reader but can make an individual answer difficult to reference precisely.
Search engines and retrieval systems already perform their own extraction, ranking and passage-selection processes. WARP does not attempt to replace those systems. It gives the publisher a consistent way to state: this is my concise answer, this is its stable identifier, this is the question it resolves, and this is the visible content that supports it.
A consuming system remains free to ignore that declaration, compare it with other information, retrieve additional context or decide that a different source is more appropriate.
[a3]
WARP starts its encoded map at the publisher’s canonical Answer Object, allows optional semantically distinct publisher-modeled fan-out intents beneath that answer, maps each F branch to visible addressable Evidence Objects, and keeps HTML, standard JSON-LD and the WARP protocol map aligned for validation.
[f1]What is the WARP retrieval hierarchy?
The WARP hierarchy is Answer Object → optional Fan-Out Question → focused answer → Evidence Object, with the visible HTML, semantic layer and WARP map kept aligned.
Evidence ↗[f2]How many fan-out questions should an answer have?
Only as many as represent materially different retrieval needs. WARP recommends a small set, commonly zero to five, and rejects redundant paraphrases as useful fan-out.
Evidence ↗[f3]What does minimum sufficient context mean?
Minimum sufficient context means retrieving the smallest answer-and-evidence unit that can resolve the current question accurately, while leaving unrelated branches unopened and unnecessary context unprocessed.
Evidence ↗How WARP Works
Start with the publisher’s main answer, called A. Add related questions, called F, only when they help. Connect each F answer to a supporting passage, called E. The WARP map records those connections. It does not record every question a user might type. In the example below, a1-f1 belongs to a1 and points to a1-f1-e1. The HTML attributes data-parent-answer and data-evidence-ref identify those links.
A: main answer → F: optional related question and answer → E: supporting passage
The goal is minimum sufficient context: enough information to answer correctly, without unrelated material. For example, a pricing question may need the price, the included work, and any conditions that change the cost. It may not need the business biography. A compatible system could select those relevant passages, but it must not leave out a condition that changes the answer.
Related questions are optional. A short answer with enough support may not need any. Where they help, WARP recommends a small set, commonly zero to five, covering different needs. Remove a proposed question as a test: if no useful fact, decision, or condition is lost, the question is probably repetitive.
The publisher writes the F questions. They suggest useful directions for further reading; they do not reveal or control the private searches or reasoning of Google, ChatGPT, or another system.
[a4]
A WARP Answer Citation is a visible identifier such as [a1] that corresponds to the stable fragment #a1, allowing the publisher, reader or compatible retrieval system to reference an individual answer within a larger page.
Link to this answerAnswer Citations and Stable Fragment IDs
An Answer Citation is a small marker such as [a1], [a2], or [a3]. It identifies an answer on the page.
Each marker connects to a normal HTML fragment ID, such as #a1. A link ending in that ID points to the answer’s location in the document.
For example, https://ericstrate.com/warp/#a4 identifies this answer. It is not a separate page or an answer-only download. The page is fetched as usual; a browser or compatible system then uses the ID to locate the relevant part.
[a5]
A WARP Answer Object is a concise answer written or approved by the publisher. It summarizes the central fact or conclusion of a section while remaining consistent with the visible supporting content.
Link to this answerPublisher-Authored Answer Objects
The Answer Object must be publisher authored or publisher approved. Automated tooling may assist in drafting it, but the publisher remains responsible for the final answer and for keeping it consistent with the supporting content.
WARP recommends keeping an Answer Object short enough to function as a direct response. One concise paragraph is normally preferable, but WARP does not impose a fixed word or token count.
The Answer Object must not materially contradict, exaggerate or omit a qualification that would change the meaning of its supporting content.
[a6]
A WARP Evidence Object, identified as E, is a visible and uniquely addressable span of normal page content that materially supports an A or F answer. An E node does not have to be contained inside the F answer; it can remain in the page’s supporting content and be referenced by stable ID.
Link to this answerEvidence Objects and Supporting Information
WARP keeps the full article or service page. Short answers are a guide to that content, not a replacement for it.
An Evidence Object (E) is a specific supporting passage with its own stable ID, such as #a1-f1-e1. A related answer can point to one or more passages when it needs explanation, evidence, or an important condition.
The evidence can stay in the main page instead of being copied into the answer panel. A compatible system can select the answer and as much supporting information as the question needs.
Evidence should add something useful: a concrete example, a necessary condition, a documented source, or a measured result. The support must fit the claim. This specification defines WARP. A service description explains the work offered. A claim about better performance needs measured results. Restating a claim is not the same as supporting it.
Every evidence link must point to exactly one visible page element. Evidence that exists only in hidden metadata does not meet this requirement.
Labeling a passage as evidence does not make it true or independently verified. Readers and AI systems still need to judge whether it supports the answer.
[a7]
WARP separates standard semantics from protocol-specific relationships. Valid Schema.org JSON-LD mirrors visible page and question-and-answer content, while a separate application/json WARP map records A → F → evidence relationships without inventing proprietary Schema.org properties.
[f1]What belongs in standard JSON-LD?
Standard JSON-LD should use valid Schema.org vocabulary for the page and visible question-and-answer content. WARP does not require inventing Schema.org properties for fan-out.
Evidence ↗[f2]What belongs in the WARP machine map?
The separate WARP application/json map expresses protocol-specific relationships such as parent Answer Objects, fan-out IDs, answer selectors and precise evidence targets.
Evidence ↗[f3]How are HTML, WARP JSON and JSON-LD kept aligned?
Stable identifiers connect the same visible question, answer and evidence across HTML, the WARP map and standard JSON-LD. A Semantic-profile implementation should validate that those representations remain substantively consistent.
Evidence ↗JSON-LD and the WARP Map
WARP uses two kinds of machine-readable information. One describes the content using standard terms. The other records WARP’s answer-and-evidence links.
Standard JSON-LD: this describes the page and its visible content using Schema.org vocabulary. This page represents main answers with ItemList, ListItem, and DefinedTerm. Related questions and answers use Question and Answer. The Schema.org Question and Answer references explain those types. WARP’s custom links between main answers, related questions, and evidence belong in the separate map.
The WARP map: this separate application/json block records which main answer a question belongs to and where its answer and evidence appear. The spec field identifies the WARP specification; page identifies the page being described. For example, answerSelector: #a1-f1-answer locates a short answer, while evidence: [#a1-f1-e1] locates its support. These are WARP conventions, not new Schema.org properties. A system must support the map to use those connections.
Keep the versions consistent: the visible page, WARP map, and JSON-LD must refer to the same questions and answers. Check that Question.name matches the visible question and Answer.text matches its answer. Check every answer and evidence selector against the page. A missing target, a changed condition, or an incorrect canonical page URL is a validation failure.
[a8]
WARP favors existing Schema.org types such as ItemList, ListItem, DefinedTerm, Question and Answer when they accurately describe visible content, while protocol-specific fan-out relationships remain in the separate WARP map rather than invented Schema.org properties.
Link to this answerWhy WARP Uses Standard Schema.org Types
WARP does not require Schema.org, search engines or AI companies to recognize a new schema type called WARPAnswer or AnswerCitation.
Instead, WARP uses existing semantic concepts where they accurately describe the information being published.
The WARP behavior comes from the relationship among the query, visible Answer Citation, stable fragment ID, publisher-authored answer, supporting HTML and matching semantic object.
This keeps the protocol compatible with ordinary web publishing rather than making the page dependent on a proprietary content format.
[a9]
Token, retrieval and energy efficiency are design goals of WARP, not guaranteed outcomes. WARP is designed for selective retrieval of the minimum sufficient answer-and-evidence context, but actual token, latency, cost or energy savings depend on the consuming system.
[f1]How could WARP reduce unnecessary context?
A compatible retriever could select the relevant A or F branch and its evidence instead of processing unrelated sections of the page. That selective retrieval is the intended efficiency mechanism.
Evidence ↗[f2]Does adding more fan-out content automatically save tokens?
No. Extra fan-out that is repetitive or always retrieved could increase context. WARP therefore favors selective, semantically distinct branches rather than publishing every possible query variation.
Evidence ↗[f3]Can WARP claim energy savings?
Not without measurement by the consuming system. Lower token use, latency, cost or energy remain hypotheses and design goals, not guaranteed outcomes of publishing WARP markup.
Evidence ↗Could WARP Reduce Processing Work?
The hypothesis is that a compatible system could select an answer and its supporting passages before sending text to a language model. To test this fairly, keep the facts and question the same. Compare WARP-based selection with a normal retrieval method that also selects relevant passages. Measure the actual input tokens and check whether both answers remain accurate and supported. This describes a test, not a proven result.
Adding WARP does not automatically reduce the text a model processes. A system that takes the whole page, including all extra answers and markup, could process more text. Selection must happen before the text reaches the model for input-token savings to occur. A shorter input is only useful if it still includes the facts and conditions needed to answer correctly.
Fewer tokens, faster responses, lower costs, and lower energy use are different outcomes. Each needs its own measurement. Energy estimates must disclose the method, hardware, and workload. A token reduction does not prove an equal reduction in cost or energy. Some systems may ignore WARP entirely.
I am testing whether WARP offers a useful improvement over ordinary content and retrieval methods. Valid markup alone does not establish that improvement.
[a10]
WARP may use cryptographic signatures or content hashes as an optional provenance extension, but cryptographic verification is not required for a basic WARP implementation.
Link to this answerOptional Cryptographic Provenance
A machine-readable answer can be copied, altered or separated from the page that originally published it. Cryptographic provenance is one possible way to address that problem.
WARP therefore allows future implementations to associate Answer Objects with signatures, content hashes or other established integrity mechanisms.
This remains an advanced and optional extension. A publisher does not need cryptographic infrastructure to implement WARP’s core relationship among queries, answers, stable identifiers, supporting content and semantic representation.
[a11]
WARP does not guarantee rankings, citations, AI visibility, lower computing costs or adoption by a search engine or AI company. It provides a publishing convention that consuming systems may choose to use.
Link to this answerWhat WARP Does Not Claim
WARP is intentionally narrow in what it claims to do.
It does not instruct Google, Bing, ChatGPT, Perplexity, Claude or another system which source to rank, retrieve or cite.
It does not create authority merely because a publisher labels something an answer, and it does not guarantee that an AI system will trust a publisher’s summary instead of independently analyzing the surrounding page.
It is not a Google ranking factor, a Schema.org standard or an industry-adopted specification.
[a12]
WARP is an experimental publishing architecture for AEO and machine retrieval that sits on top of traditional SEO. It does not replace crawlability, indexation, useful content, internal linking, authority or other established search fundamentals.
Link to this answerHow WARP Relates to SEO, AEO and GEO
WARP is most relevant to Answer Engine Optimization because it deals directly with identifying and addressing concise answers.
It can also be considered within Generative Engine Optimization because generative systems frequently use retrieved source material when constructing responses.
Neither changes the underlying requirement for good SEO. A WARP implementation on an inaccessible, unhelpful or untrusted page does not solve those problems.
This is why WARP is implemented on EricStrate.com as an additional information architecture rather than as a replacement for normal search optimization.
[a13]
A basic WARP implementation identifies the page’s primary query, maps important sections to stable Answer Objects and visible support, optionally nests semantically distinct fan-out questions beneath those answers, maps each fan-out to precise evidence, and keeps standard JSON-LD plus the WARP protocol map aligned with the visible HTML.
Link to this answerWARP Implementation Example
A simplified visible answer unit can be implemented with ordinary HTML:
<article
  data-warp-document="true"

  data-primary-intent="protocol definition">

  <div id="a1"
       data-warp="answer"
       data-support-ref="#support-a1">
    <details class="wacp-citation">
      <summary>[a1]</summary>
      <p>Primary concise answer...</p>

      <details id="a1-f1"
               data-warp="fanout"
               data-parent-answer="a1"
               data-evidence-ref="#a1-f1-e1">
        <summary>[f1] Related retrieval question</summary>
        <p id="a1-f1-answer">Focused fan-out answer...</p>
      </details>
    </details>
  </div>

  <p id="a1-f1-e1"
     data-warp-evidence="true"
     data-evidence-for="a1-f1">
    Visible supporting evidence...
  </p>
</article>
Standard JSON-LD should use established Schema.org vocabulary that matches the visible content. WARP-specific parent, fan-out and evidence relationships can be expressed separately in an application/json protocol map using the same stable identifiers. The actual USER QUESTION remains external to that map; optional query-intent metadata describes the information need rather than enumerating every possible phrasing.
[a14]
A conforming WARP page keeps stable Answer Objects and visible support, treats fan-out as optional and semantically distinct, maps any fan-out branch to precise evidence, and preserves consistency across visible HTML and any machine-readable representations the implementation exposes.
[f1]What is three-way consistency validation?
For WARP Semantic conformance, the visible HTML, the WARP application/json map and the standard JSON-LD should identify the same questions and materially consistent answers using stable IDs.
Evidence ↗[f2]How is fan-out diversity validated?
Fan-out branches should represent different information needs, not keyword or wording variants of one question. A validator can flag duplicate IDs and exact duplication, while semantic diversity still requires editorial judgment or a separate similarity check.
Evidence ↗[f3]Is the nested visual design required?
No. Progressive disclosure is the recommended WARP presentation profile because it preserves the low-noise WARP experience, but visual styling remains non-normative if the semantic relationships and accessibility remain intact.
Evidence ↗WARP Conformance Requirements
Required
- Identify one primary Answer Object and its broad query intent; do not treat one literal USER QUESTION string as exhaustive.
- Give every Answer Object a stable fragment identifier that is not reassigned to unrelated content.
- Associate each Answer Object with explicit visible support.
- Keep the concise answer materially consistent with its visible support.
- Keep the page useful if every WARP-specific data attribute is ignored.
- When fan-out is used, give each F branch a unique child identifier, a focused visible answer and at least one stable E target.
- Do not use fan-out solely to repeat keyword or wording variants of the same information need.
Semantic profile
A WARP Semantic implementation should keep the visible HTML, WARP application/json map, and standard JSON-LD consistent. This is called three-way consistency. All three must identify the same question and preserve the answer’s meaning and important conditions. Exact wording is preferred for short F answers. The map starts with the publisher’s answer, not the user’s actual search. To check a branch, compare its visible question and answer with the map and JSON-LD, then follow every evidence link.
Fan-out diversity is a semantic requirement rather than a keyword-count rule. F branches are publisher-modeled retrieval intents and should resolve materially different information needs. Duplicate identifiers and exact duplicate questions are machine-checkable; deeper semantic redundancy may require editorial review or a similarity test. For example, ‘What does it cost?’ and ‘What is the price?’ would normally be redundant siblings. ‘What is included?’ and ‘Who implements the changes?’ address different decisions. Exact-string checks cannot establish that distinction on their own.
Recommended citation presentation profile
WARP preserves the low-noise WARP presentation profile: small link-colored A markers with no decorative background. Fan-out questions are progressively disclosed inside the opened A panel and use smaller subordinate markers. Evidence identifiers do not need to be shown visually when an ordinary evidence link is sufficient. Styling remains non-normative. An inline, always-visible answer can preserve the same A, F and E relationships. A disclosure-based presentation should also work by keyboard, reveal linked branches, and let an Evidence link move the reader out of the panel to its supporting passage.
Validator checks
- Every A, F and E identifier is unique in the rendered DOM.
- Every F identifies one valid parent A and one visible focused answer.
- Every E reference resolves to exactly one visible element; an E node may live outside the F answer.
- Each referenced E materially supports the F answer that points to it and should add context, a qualification, an example, a documented source or an observed result beyond a paraphrase.
- Sibling F nodes represent distinct information needs rather than paraphrastic variants.
- The WARP map references only selectors and evidence IDs that actually exist in the HTML.
- The WARP map
pagevalue matches the implementation page’s canonical URL exactly;specidentifies the canonical WARP specification separately. - When standard JSON-LD represents an F question,
Question.namematches the visible F question andAnswer.textmatches the visible focused F answer. - For the Interactive profile, a direct F fragment such as
#a1-f1should reveal the parent A panel and the targeted F branch.
Conformance profiles
WARP Core covers the required visible HTML relationships. WARP Semantic adds aligned machine-readable representations and validation. WARP Interactive adds optional citation controls, nested fan-out interactions and tested accessibility behavior.
Optional
- Fan-out nodes when no meaningful secondary retrieval need exists.
- Cryptographic signatures or content hashes.
- Interactive citation popovers and hover behavior.
- Additional provenance metadata.
[a15]
WARP uses versioned specifications while keeping a permanent canonical web location. EricStrate.com/warp/ is the canonical specification page, while the open-source repository provides implementation documentation, examples and source-control history.
Link to this answerDevelopment and the Open Specification
The permanent canonical location of the Web Answer Retrieval Protocol is:
https://ericstrate.com/warp/
The public specification remains at one canonical URL. Revisions are documented in the protocol history rather than promoted as separate public versions.
WARP is also developed openly through the Web Answer Retrieval Protocol GitHub repository. Repository documentation and release history can evolve separately from the canonical web specification and should be synchronized when a new version is formally published.
[a16]
WARP retains the low-noise citation design and explicit Answer-to-Support mapping of WARP, then adds optional nested fan-out questions, precise evidence targets, minimum-sufficient-context guidance, selective-retrieval design goals and a separate protocol map alongside valid standard JSON-LD.
[f1]What does WARP preserve from earlier revisions?
WARP retains stable A citations, explicit Answer-to-Support mapping, validator-oriented conformance, semantic mirroring and the small low-noise citation presentation introduced in WARP.
Evidence ↗[f2]What does the current WARP architecture add?
WARP adds optional nested fan-out nodes, precise evidence targets, selective-retrieval design goals, minimum-sufficient-context guidance and a separate protocol map alongside valid standard JSON-LD.
Evidence ↗[f3]Why was the current WARP architecture piloted before broader deployment?
The 6.0 structure is being tested on the canonical WARP specification first so its visual behavior, semantic mappings and validation rules can be refined before wider implementation.
Evidence ↗What Changed in WARP?
WARP keeps the parts of 5.0 that are working well: stable [a1]-style citations, explicit Answer-to-Support mapping, validator-oriented conformance rules, semantic mirroring and a small background-free citation presentation that stays out of the reader’s way. Existing links to an A identifier should continue to resolve to the same subject as the page evolves. The ordinary section remains readable on its own, and its support relationship stays available even when the interactive panel is unused.
The new layer is hierarchical: A → F → E. An Answer Object may expose optional f1, f2 and similar publisher-modeled fan-out intents inside its expanded panel. Each F has its own focused answer and can point to one or more visible Evidence Objects identified with stable e1, e2 and similar IDs. WARP also formalizes selective retrieval and minimum sufficient context as design goals. A useful implementation check follows the whole route: A supplies the canonical answer, F resolves a narrower question, and E supplies a concrete explanation, source, example or result. Assigning an E identifier to a paraphrase alone provides little additional substantiation.
Machine-readable structure is split deliberately: standard JSON-LD uses valid established vocabulary, while the separate WARP map records protocol-specific A → F → evidence relationships. This avoids inventing unsupported Schema.org properties.
The current WARP architecture was piloted first on the canonical WARP specification page. The implementation remains experimental and does not claim that a search engine or AI system recognizes WARP, uses the same fan-out questions, or will rank or cite a page because WARP is present. Pilot checks cover unique IDs, resolving selectors, consistent answers and working keyboard and link navigation. Those checks establish implementation behavior. A separate comparison is needed to establish any retrieval, citation or efficiency benefit.
Protocol History
October 22, 2026: clearer explanations
Revised the introduction and selected supporting explanations to make WARP easier to understand. The existing A and F answer text, citation IDs, evidence links, and machine-readable mappings were retained. Supporting passage wording changed, so observations before and after this edit should be compared against the corresponding saved page content. This editorial revision is not evidence of a performance improvement.
Earlier public revisions were published under the original WACP name. The numbered revisions are retained here as development history; the current public protocol is simply WARP.
Version 6.0 — September 2026
Added the A → F → E hierarchy: canonical Answer Objects, optional publisher-modeled fan-out intents and visible addressable Evidence Objects, plus selective-retrieval and minimum-sufficient-context design goals and a separate WACP protocol map alongside valid standard JSON-LD.
Preserved the WACP 5.0 low-noise visual presentation by placing fan-out interactions inside the existing A citation panel rather than adding new default markers throughout the page.
Added three-way consistency guidance for visible HTML, WACP JSON and standard JSON-LD, while keeping fan-out metadata explicitly publisher-authored and experimental.
Version 5.0 — September 2026
Added explicit Answer-to-Support mapping so each concise Answer Object can identify the visible support that explains, qualifies or evidences it.
Added validator-oriented conformance rules and named Core, Semantic and Interactive implementation profiles.
Added a recommended citation presentation profile: small, uniform, link-colored markers with no decorative background and a larger invisible interaction target.
Version 4.0 — September 2026
Added an explicit publisher-authored query graph connecting one primary query to legitimate fan-out questions, individual Answer Objects, visible supporting content and the matching semantic layer.
Added document-level metadata for the primary query and intent, plus answer-level metadata identifying query role and the question resolved by each Answer Object.
Retained the WACP 3.0 requirements for stable fragment identifiers, visible supporting context, accessible citation controls and semantic mirroring.
Version 3.0 — August 2026
Established the dual-layer implementation used across EricStrate.com: visible Answer Objects with stable fragment identifiers plus a matching semantic ItemList / ListItem / DefinedTerm representation.
Earlier versions
Earlier public drafts explored answer citations, semantic answer blocks, token-efficiency concepts and optional provenance extensions. Historical implementation material is preserved through the project’s source-control history.
WARP in Practice
This page is the first WARP pilot implementation. It preserves the WARP A-citation presentation while selected Answer Objects expose nested fan-out questions and precise evidence targets for testing before broader deployment.
WARP is also used on selected pages across EricStrate.com. Those implementations are experiments. Their presence does not imply adoption or endorsement by a search engine, AI company, Schema.org or automotive manufacturer.
The Google AI search service page’s WARP implementation connects canonical answers, related buyer questions and visible supporting evidence. It provides a live example of the publishing architecture; any effect on retrieval, citations or inquiries requires separate measurement.
The Claude AI search service example also connects concise answers, related customer questions and evidence anchors while clearly distinguishing experimental WARP structure from verified Claude citation results.
WARP Specification Disclosure
The Web Answer Retrieval Protocol is an independent proposal created by Eric Strate. WARP is not endorsed by Google, Microsoft, OpenAI, Anthropic, Schema.org, the W3C or an automotive manufacturer. It is not a search ranking factor and does not guarantee inclusion, ranking or citation in search or AI-generated results. Performance and efficiency claims require empirical validation by the systems that consume WARP-formatted content.
WARP is also being tested on a deliberately unserious live experiment: the Best SEO Expert experiment .